Duplicate content is one of the most common technical SEO challenges, and canonical tags are one of the primary tools for managing it. When you run a site audit, you may see warnings about pages missing canonical links, leading to the question: are pages without canonical links bad for SEO? The answer is that a missing canonical tag is not automatically harmful, but it can create problems on websites where duplicate or similar pages exist. This guide explains what canonical tags do, how search engines handle pages without them, and how to implement them effectively.
How AAMAX.CO Resolves Canonical and Duplicate Content Issues
Canonicalization problems can quietly dilute rankings across an entire website, especially on ecommerce stores and large content sites. AAMAX.CO is a full-service digital marketing company offering web development, digital marketing, and SEO services worldwide, and they identify duplicate URLs, configure canonical tags correctly, and fix the underlying technical causes. With developers and SEO specialists on the same team, they implement solutions at the template level for lasting results. Their SEO services include thorough technical audits that uncover these hidden issues.
What Is a Canonical Link?
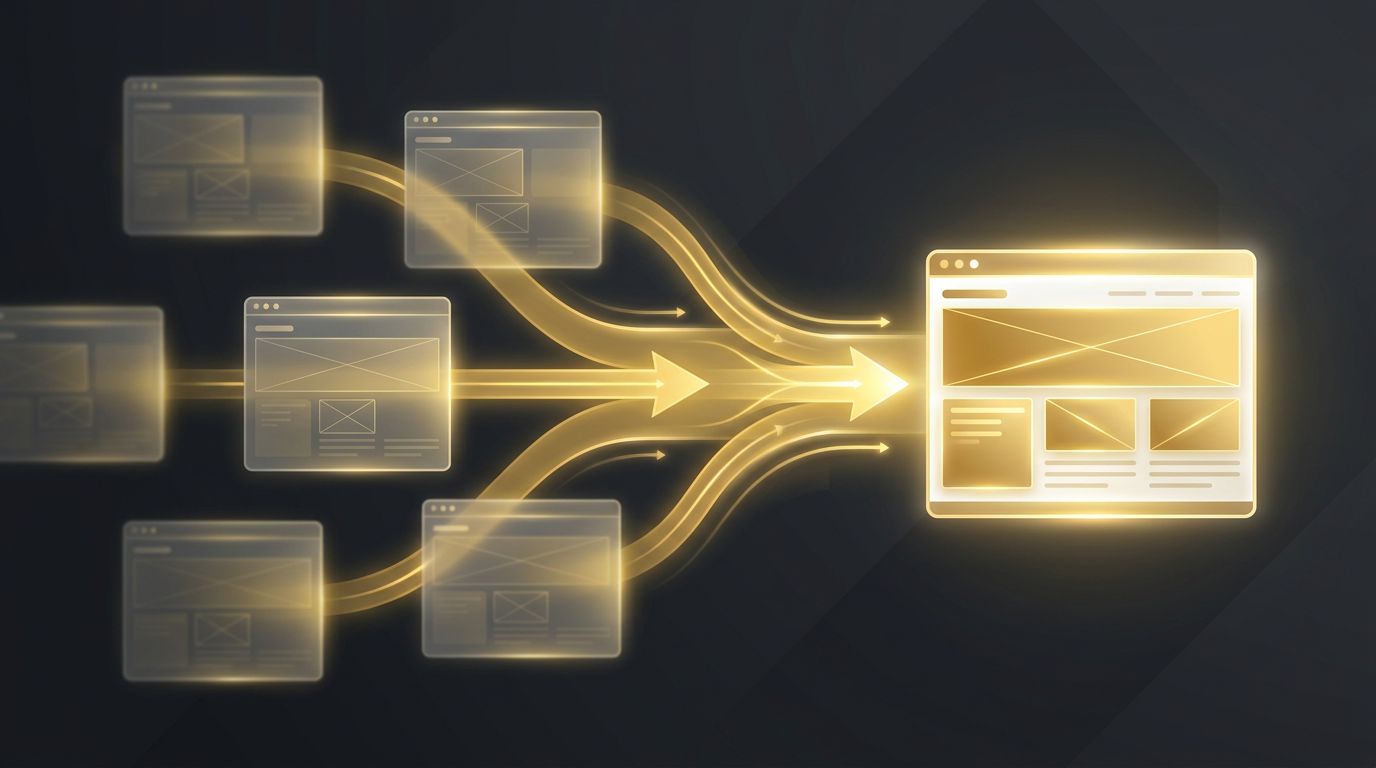
A canonical link, or canonical tag, is an HTML element placed in the head section of a page that tells search engines which URL is the preferred version of that content. It looks like this: <link rel="canonical" href="https://example.com/page/">. When multiple URLs contain the same or very similar content, the canonical tag signals which one should be indexed and shown in search results, and where ranking signals should be consolidated.
Why Duplicate URLs Happen
Duplicate content is often created unintentionally. Common causes include:
- HTTP and HTTPS versions of the same page.
- WWW and non-WWW versions of URLs.
- Trailing slash variations.
- URL parameters for tracking, sorting, or filtering.
- Ecommerce products accessible through multiple category paths.
- Printer-friendly or AMP versions of pages.
- Syndicated content published on other websites.
How Search Engines Handle Pages Without Canonicals
If a page does not have a canonical tag, search engines will attempt to determine the canonical version themselves. Google considers signals such as redirects, internal linking patterns, sitemap inclusion, HTTPS usage, and URL structure to choose the most representative version. In many cases, Google makes the right choice. However, when signals conflict, Google may select a different URL than you intended, split ranking signals across duplicates, or waste crawl resources on redundant pages.
When Missing Canonicals Are Not a Problem
For a small website with unique content on every page and clean URL handling, missing canonical tags may have little practical impact. If each page is accessible through only one URL and there are no parameter or protocol variations, search engines have no duplicates to choose between. That said, adding self-referencing canonicals is still a helpful safeguard.
When Missing Canonicals Can Hurt SEO
Missing canonical tags become problematic on sites with duplicate or near-duplicate content. Potential issues include:
- Diluted ranking signals: Backlinks and engagement may be split across multiple versions of the same page.
- Wrong URL in search results: Search engines might display a parameter-based or less user-friendly URL.
- Crawl inefficiency: Large sites may waste crawl budget on duplicate URLs instead of important pages.
- Syndication confusion: When content is republished elsewhere, the original may be outranked by the copy.
What Is a Self-Referencing Canonical?
A self-referencing canonical is a canonical tag on a page that points to its own URL. It is considered a best practice because it clearly states the preferred URL and protects against duplicates created by parameters, tracking codes, or scrapers. Most modern CMS platforms and SEO plugins add self-referencing canonicals automatically.
Best Practices for Canonical Tags
- Add self-referencing canonicals to all indexable pages.
- Use absolute URLs, including the protocol and domain.
- Point canonicals only to pages that return a 200 status code and are indexable.
- Avoid canonicalizing to pages with noindex tags or redirects.
- Keep canonicals consistent with internal links, sitemaps, and hreflang tags.
- Use only one canonical tag per page.
- Use 301 redirects instead of canonicals when a duplicate page should not exist at all.
Common Canonical Mistakes
Canonical tags can cause harm if implemented incorrectly. Common errors include pointing all pages to the homepage, canonicalizing paginated pages to the first page when they contain unique items, using relative URLs incorrectly, conflicting canonicals set by multiple plugins, and canonicalizing to URLs blocked by robots.txt. Remember that canonical tags are hints, and search engines may ignore them if other signals contradict them.
How to Audit Canonical Tags
Use site crawlers to identify pages missing canonicals, pages with multiple canonicals, and canonicals pointing to non-indexable URLs. In Google Search Console, the URL Inspection tool shows both the user-declared canonical and the Google-selected canonical, helping you spot discrepancies.
Final Thoughts
Pages without canonical links are not inherently bad for SEO, but they leave search engines to guess which version of your content to prioritize. On sites with duplicate URLs, parameters, or syndicated content, this can dilute rankings and waste crawl budget. Implementing self-referencing canonicals and correct canonicalization for duplicates is a simple, effective way to protect your SEO and ensure the right pages earn visibility.
Want to publish a guest post on aamconsultants.org?
Place an order for a guest post or link insertion today.