If you have ever wondered why a new page on your website does not appear in search results, the answer often lies in two fundamental processes: crawling and indexing. These terms are frequently used interchangeably, but they describe very different stages in how search engines work. Crawling is about discovery, while indexing is about understanding and storage. A page can be crawled without being indexed, and if it is not indexed, it cannot rank. Understanding the difference between crawling and indexing in SEO helps you diagnose visibility problems, prioritize technical fixes, and ensure your most important content gets found.
Get Expert Technical SEO Support From AAMAX.CO
Crawling and indexing issues can be difficult to diagnose without the right expertise. AAMAX.CO is a full-service digital marketing company offering Web Development, Digital Marketing, and SEO Services worldwide. Their technical specialists analyze crawl data, review server logs, fix indexation problems, and optimize site architecture so search engines can discover and store your most valuable pages. Because they also build websites, they can resolve code-level issues that block crawlers. Businesses seeking professional search engine optimization can trust them to strengthen the technical foundation that rankings depend on.
What Is Crawling?
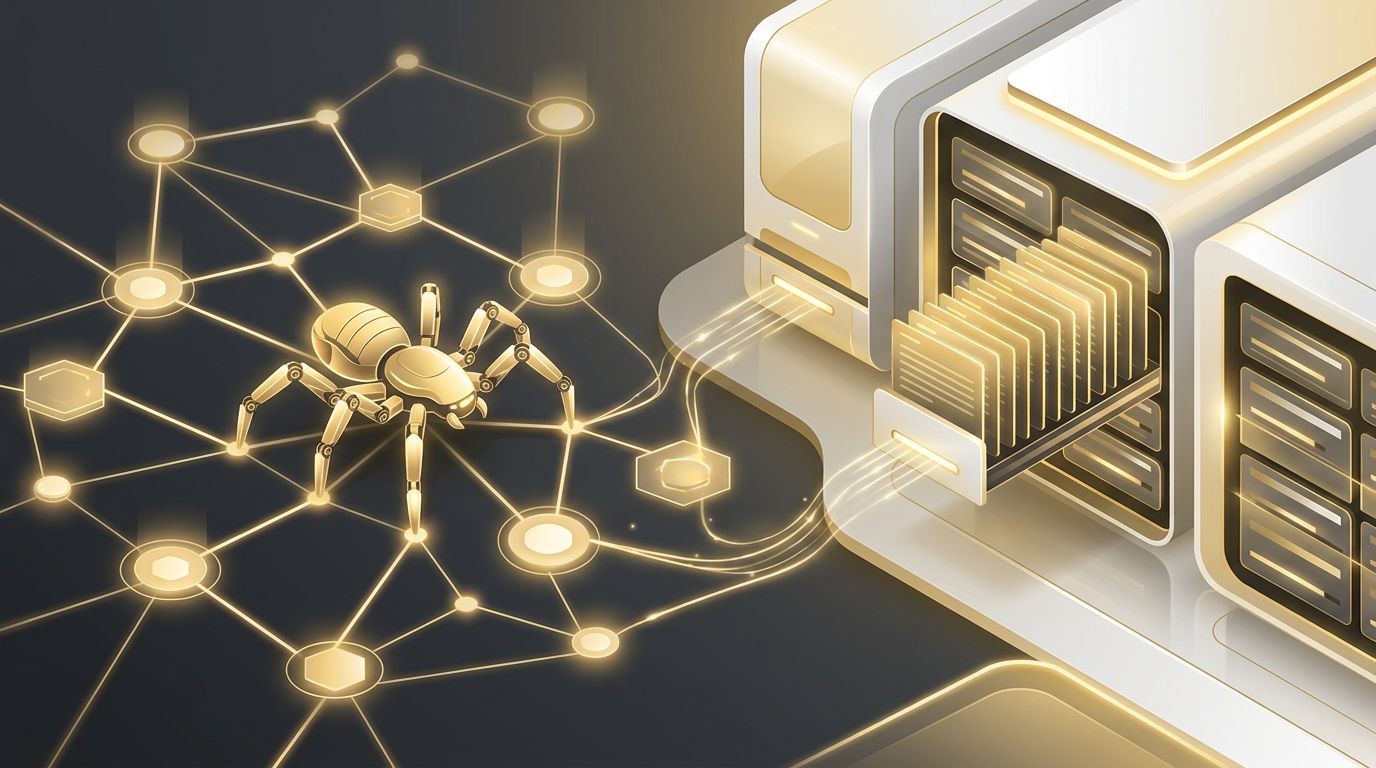
Crawling is the process by which search engines send automated programs, often called bots, spiders, or crawlers, to discover content on the web. Google's crawler is known as Googlebot. These bots start with a list of known URLs, visit those pages, and follow the links they find to discover new pages. They also check sitemaps submitted by website owners.
During crawling, the bot downloads the page's HTML and associated resources such as CSS, JavaScript, and images. Modern crawlers can render JavaScript, which allows them to see content loaded dynamically. However, rendering is resource-intensive and may happen later than the initial crawl.
Crawling is limited by what is called crawl budget, the number of pages a search engine is willing and able to crawl on your site within a given timeframe. For small sites, crawl budget is rarely a concern. For large websites with thousands or millions of URLs, inefficient crawling can mean important pages are discovered slowly or not at all.
What Is Indexing?
Indexing happens after crawling. Once a search engine has fetched a page, it analyzes the content to understand what the page is about. It evaluates text, headings, images, structured data, links, and other signals. It also checks for duplicates and decides which version of a page should be considered canonical.
If the page meets quality standards and is not blocked, the search engine stores it in its index, a massive database of web content. Only indexed pages are eligible to appear in search results. Think of crawling as a librarian collecting books and indexing as cataloging them on shelves so readers can find them later.
Key Differences at a Glance
- Purpose: Crawling discovers pages; indexing evaluates and stores them.
- Order: Crawling always comes first; indexing depends on a successful crawl.
- Control methods: Robots.txt primarily controls crawling, while the noindex directive controls indexing.
- Outcome: A crawled page is known to the search engine; an indexed page can appear in search results.
Why a Page Might Be Crawled but Not Indexed
Google Search Console often reports statuses like "Crawled – currently not indexed" or "Discovered – currently not indexed." These messages indicate that the search engine knows about the page but has chosen not to add it to the index, at least for now. Common reasons include:
- Thin or low-value content that offers little unique information.
- Duplicate or near-duplicate content already represented by another URL.
- A noindex meta tag or HTTP header instructing search engines not to index.
- Canonical tags pointing to a different page.
- Weak internal linking that signals the page is unimportant.
- Technical issues like soft 404 errors or rendering problems.
Robots.txt vs. Noindex: A Common Mistake
Many site owners block pages in robots.txt hoping to keep them out of search results. However, robots.txt prevents crawling, not indexing. If other sites link to a blocked URL, it can still be indexed without its content, sometimes appearing with a generic description. Conversely, if you add a noindex tag to a page but also block it in robots.txt, search engines cannot crawl the page to see the noindex instruction. To remove a page from the index, allow crawling and use noindex.
How to Improve Crawling
- Submit an XML sitemap containing only canonical, indexable URLs.
- Build a logical site structure where important pages are a few clicks from the homepage.
- Use internal links generously and descriptively.
- Fix broken links and redirect chains that waste crawl resources.
- Improve server response times so bots can fetch more pages efficiently.
- Limit infinite URL variations caused by filters, parameters, and session IDs.
How to Improve Indexing
- Create unique, substantial content that satisfies search intent.
- Consolidate duplicate pages and use canonical tags correctly.
- Ensure important content is visible in rendered HTML, not hidden behind user interactions.
- Remove accidental noindex tags from templates.
- Use the URL Inspection tool in Search Console to request indexing for priority pages.
- Add structured data to help search engines understand page context.
Crawling, Indexing, and AI Search
AI-powered search experiences also rely on crawled and indexed content to generate answers. If your pages are not accessible or well understood, they are less likely to be cited in AI summaries. Clear structure, authoritative content, and strong technical foundations support visibility in both traditional results and generative engines. Integrating these efforts into a wider digital marketing plan ensures your brand stays discoverable everywhere users search.
Conclusion
The difference between crawling and indexing in SEO is simple once you break it down: crawling is how search engines find your pages, and indexing is how they understand and store them for search results. Both stages must work smoothly for your content to rank. By optimizing site structure, managing crawl efficiency, using the correct directives, and publishing high-quality content, you give search engines every reason to discover and index your most important pages.
Want to publish a guest post on aamconsultants.org?
Place an order for a guest post or link insertion today.