Few topics in SEO cause as much confusion and anxiety as duplicate content. Many website owners worry that having similar or repeated content will trigger a penalty and destroy their rankings. The reality, according to Google's own guidance, is more nuanced and far less alarming than the myths suggest. Understanding what duplicate content actually is, how search engines handle it, and when it genuinely becomes a problem can help you focus your energy on the issues that truly matter rather than worrying about imaginary threats.
What Duplicate Content Really Means
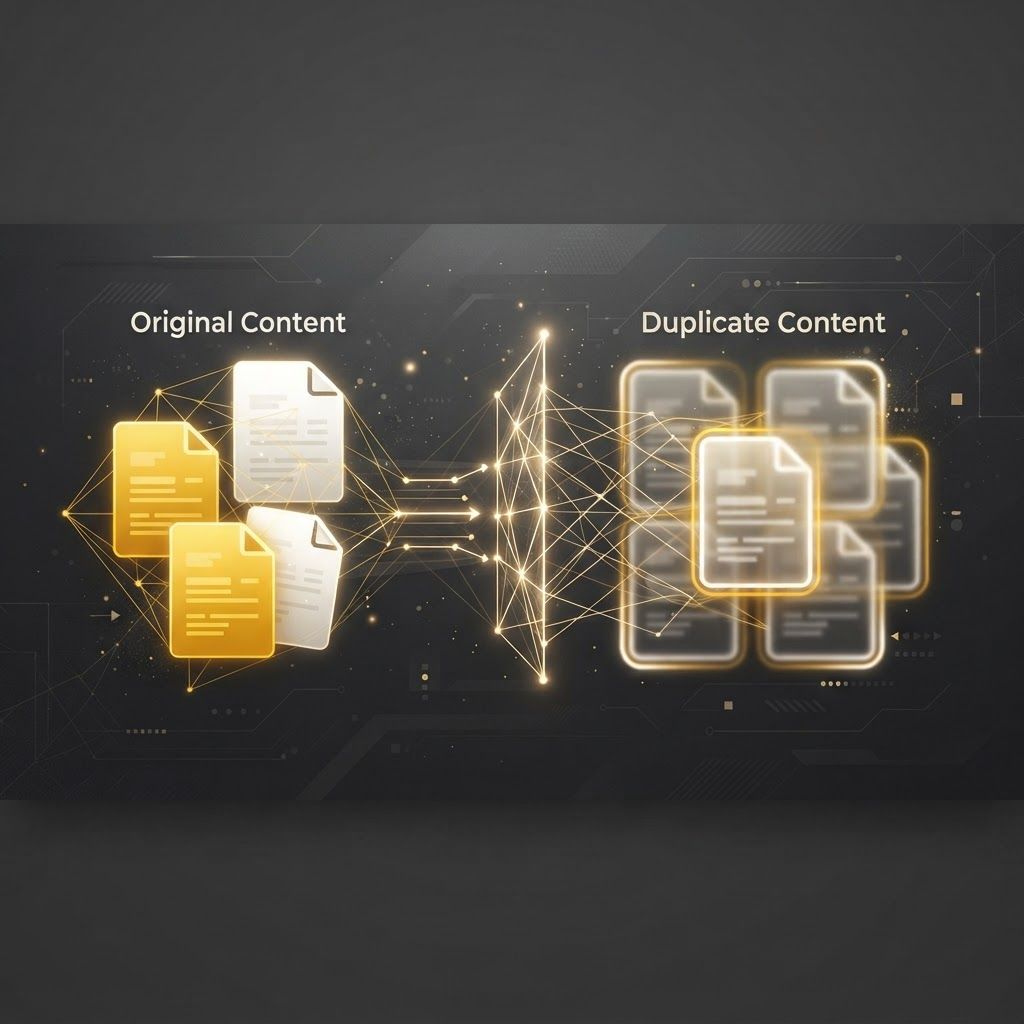
Duplicate content refers to blocks of content that appear in more than one place, either within a single website or across multiple websites. This can happen for many innocent reasons, such as printer-friendly versions of pages, product descriptions that appear under multiple URLs, or content syndicated across sites. It is important to understand that duplicate content is extremely common on the web and often arises from ordinary technical situations rather than any attempt to deceive. Recognizing this helps put the issue into perspective and reduces unnecessary fear.
How AAMAX.CO Helps Keep Content Healthy
Identifying and resolving content issues across a large website requires both technical insight and careful attention to detail. AAMAX.CO is a full-service digital marketing company that helps businesses worldwide maintain clean, well-structured websites as part of their SEO services. Their team knows how to spot situations where duplicate content might cause confusion for search engines and how to resolve them properly. By addressing these issues methodically, they help their clients ensure that the right pages receive the credit they deserve, supporting stronger and more reliable performance in search results.
What Google Actually Says
Google has been clear that most duplicate content is not a cause for punishment. In the vast majority of cases, when Google encounters duplicate content, it simply chooses which version to display in search results and consolidates signals toward that version. There is no automatic penalty for having duplicate content that arises from normal website operations. The concept of a duplicate content penalty is largely a myth. Google's primary concern is delivering the best results to users, so it filters duplicates rather than punishing sites for their existence.
When Duplicate Content Becomes a Problem
While ordinary duplication is rarely harmful, there are situations where it can cause real issues. The most common problem is not a penalty but confusion, where search engines struggle to determine which version of a page to rank. This can dilute your visibility, split signals between pages, and lead to the wrong page appearing in results. A more serious concern arises when duplicate content is created deliberately and deceptively to manipulate rankings or copy others' work, as this can genuinely violate guidelines. For most legitimate websites, however, the practical issue is clarity rather than punishment.
Using Canonical Tags
One of the most effective ways to manage duplicate content is the canonical tag. This is a simple piece of code that tells search engines which version of a page you consider the primary, preferred one. When you use canonical tags correctly, you help search engines consolidate signals toward the version you want to rank, resolving the confusion that duplication can cause. This is especially useful for situations like product pages accessible through multiple URLs or content that legitimately appears in more than one place on your site.
Practical Steps to Avoid Issues
Beyond canonical tags, several practical habits help you avoid duplicate content problems. Aim to create original, valuable content for each important page rather than reusing the same text across many pages. When you must use similar content, such as standard product descriptions, consider adding unique details to differentiate each page. Maintain a clean site structure with consistent URLs, and use redirects appropriately when content moves. These straightforward practices, often part of a broader digital marketing and technical strategy, prevent most duplication issues before they arise.
Duplicate Content Across Different Websites
Sometimes content appears on multiple websites, such as when articles are syndicated or when others copy your work. If you syndicate your content, it is wise to ensure that the original source is clearly identified, ideally through canonical tags or agreements that point back to your site. If someone copies your content without permission, the situation is generally handled by search engines recognizing the original source, though you can take additional steps if needed. In both cases, the goal is to help search engines understand which version is authoritative.
Focusing on What Truly Matters
Perhaps the most valuable takeaway is that duplicate content should not dominate your SEO worries. Rather than obsessing over minor duplication that occurs naturally, direct your energy toward creating genuinely helpful, original content and providing an excellent user experience. Address duplication where it causes real confusion, use canonical tags sensibly, and then move on to the strategies that drive meaningful growth. This balanced perspective keeps you focused on the work that actually improves your rankings and serves your audience.
Final Thoughts
So, does duplicate content hurt SEO? According to Google's guidance, ordinary duplicate content does not trigger a penalty, but it can cause confusion that dilutes your visibility if left unmanaged. By understanding what duplicate content really is, using tools like canonical tags, and following sensible practices, you can prevent problems without unnecessary anxiety. Focus your efforts on creating original, valuable content and maintaining a clean website, and duplicate content will remain a manageable technical detail rather than a source of fear.
Want to publish a guest post on aamconsultants.org?
Place an order for a guest post or link insertion today.