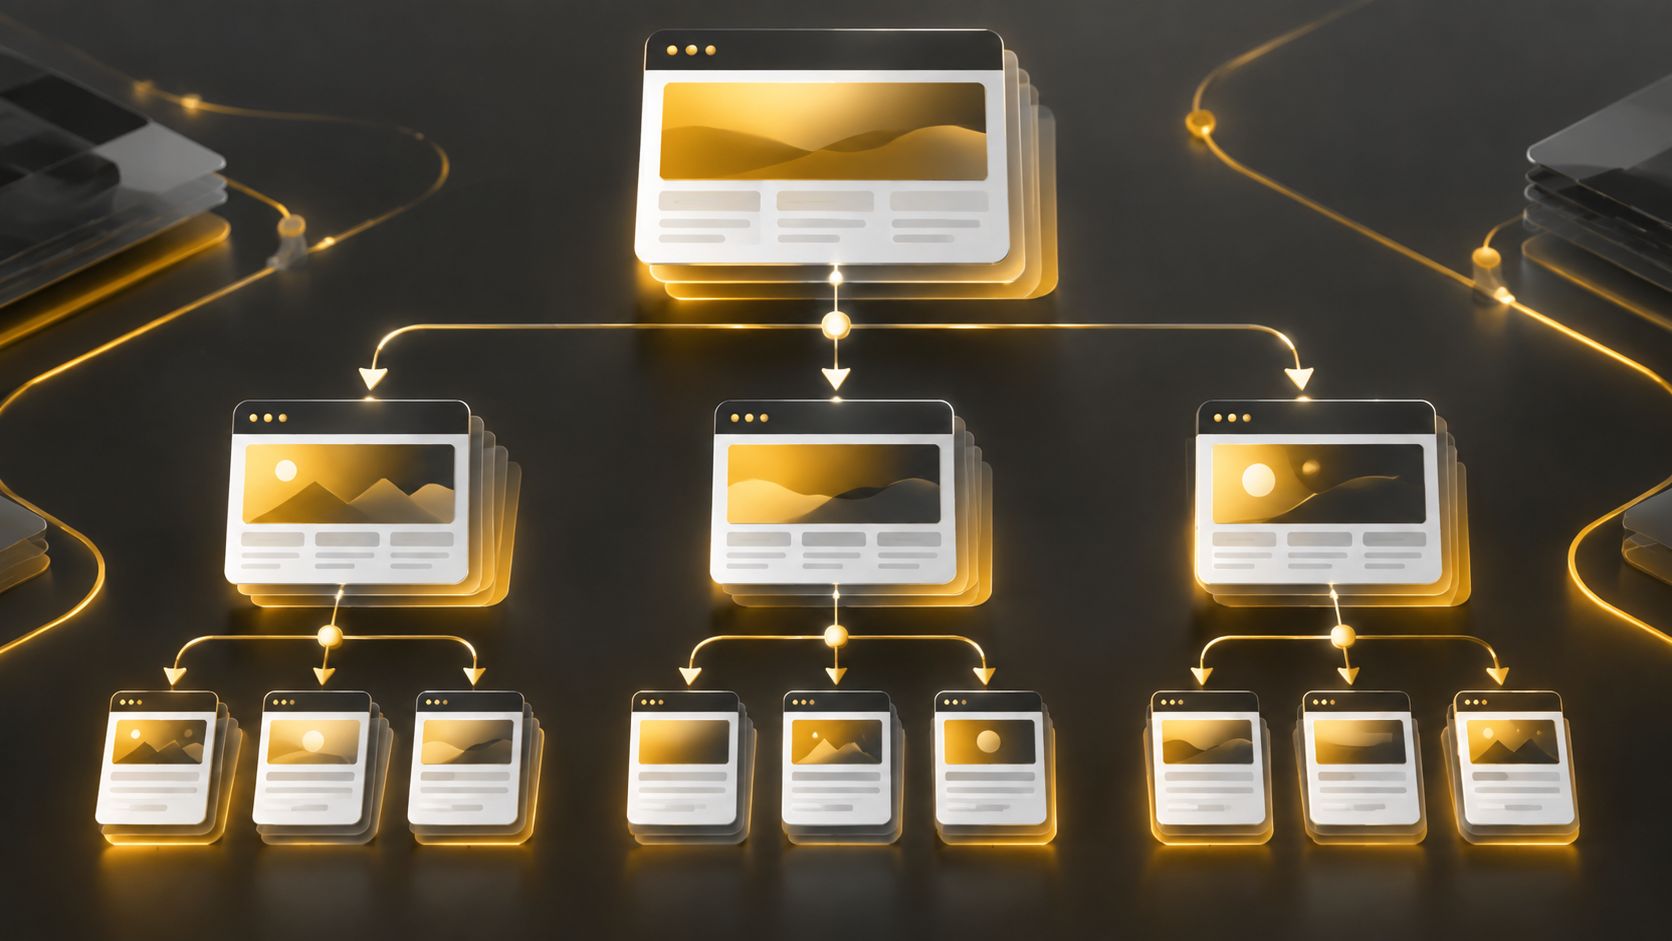
Pagination is the practice of splitting a large set of content, such as blog archives, product listings, or forum threads, across multiple numbered pages. While it improves usability by keeping pages manageable, it also introduces complexity for search engines that must crawl, understand, and index the sequence. Handled poorly, pagination can waste crawl budget, dilute ranking signals, and create duplicate content problems. Handled well, it helps search engines discover deep content while preserving the authority of key pages. Understanding this balance is essential for any site with large content sets.
How AAMAX.CO Can Help With Technical SEO
Pagination is just one of many technical factors that determine how effectively a site performs in search. AAMAX.CO is a full-service digital marketing company offering web development, digital marketing, and SEO services worldwide, and their technical team specializes in diagnosing and fixing crawl and indexing issues like pagination, faceted navigation, and duplicate content. Because they combine development expertise with SEO strategy, they can implement solutions correctly at the code level rather than applying superficial fixes. For ecommerce stores and content-heavy sites, their guidance ensures that large catalogs remain fully discoverable and efficiently crawled.
How Search Engines View Paginated Content
When search engines encounter a paginated series, they attempt to understand the relationship between pages. Historically, the rel=next and rel=prev markup signaled this sequence, but major engines no longer rely on it. Today, engines treat each paginated page as a standalone URL and use on-page links and content to infer the relationship. This means the way you link, canonicalize, and structure paginated pages directly influences how deep content gets discovered and how ranking signals flow through the site.
Common Pagination Problems
Several issues arise when pagination is implemented carelessly. Duplicate or near-duplicate content can appear when page titles and meta descriptions are identical across the series. Crawl budget can be wasted when search engines spend time on countless low-value paginated URLs instead of important pages. Thin content problems emerge when individual pages offer little unique value. Perhaps most damaging, ranking signals can be split across many pages instead of consolidating on the content that matters, weakening overall performance.
Canonical Tags and Pagination
A frequent mistake is pointing every paginated page's canonical tag back to the first page. This tells search engines to ignore pages two and beyond, which can prevent products or articles on those pages from being indexed and discovered. The generally recommended practice is for each paginated page to have a self-referencing canonical, so page two points to page two. This keeps deep content discoverable while avoiding false duplicate signals. A view-all page can be an alternative when it loads quickly and content volume is reasonable.
Best Practices for Pagination
To implement pagination effectively, ensure each page has a unique, self-referencing canonical URL. Use crawlable anchor links with real href attributes so engines can follow the sequence, avoiding JavaScript-only navigation that hides links. Differentiate title tags and meta descriptions where practical, for example by including the page number. Keep paginated URLs clean and consistent, and avoid indexing infinite scroll implementations unless paginated fallback URLs exist. Finally, make sure important products or articles are also reachable through category pages, internal links, and sitemaps so they do not depend solely on deep pagination.
Pagination vs Infinite Scroll
Many modern sites use infinite scroll for a smoother experience, but this can hide content from crawlers that do not scroll like users. The safest approach is to pair infinite scroll with traditional paginated URLs that load content on their own. This gives users a seamless experience while guaranteeing that search engines can access every page through standard links. Without this fallback, deep content may never be indexed.
Crawl Budget Considerations
For large sites, crawl budget is a real constraint. If search engines waste resources crawling endless paginated variations, they may not reach genuinely important pages. Strategic use of internal linking, XML sitemaps, and, where appropriate, noindex directives on low-value filter combinations helps direct crawlers toward the content that drives traffic and revenue. The goal is to make crawling efficient rather than exhaustive.
Monitoring Paginated Content Over Time
Pagination is not a set-and-forget task, especially on sites where content changes frequently. Regularly review how many paginated URLs are indexed, whether deep pages are being crawled, and if important products or articles remain discoverable. Search console coverage reports reveal whether engines are wasting effort on low-value pages or successfully reaching the content that matters. Log file analysis can show exactly how crawlers move through paginated series, exposing inefficiencies. As catalogs grow and categories expand, pagination structures should be revisited to ensure they still serve both users and search engines well. Ongoing monitoring catches problems early, before they quietly erode the visibility of deep, valuable content that depends on healthy pagination to be found.
Conclusion
Pagination affects SEO by shaping how search engines crawl, index, and value deep content. Poor implementation leads to duplicate content, wasted crawl budget, and diluted signals, while proper implementation keeps large catalogs discoverable and efficient. By using self-referencing canonicals, crawlable links, unique metadata, and smart internal linking, sites can ensure their paginated content supports rather than undermines their search performance, keeping every valuable page within reach of both users and search engines.
Want to publish a guest post on aamconsultants.org?
Place an order for a guest post or link insertion today.