Every page that appears in search results has gone through two essential steps: crawling and indexing. Search engines use automated programs to discover web pages and then store information about those pages in a massive database. If either step fails, your page cannot rank, no matter how valuable its content may be. Understanding how crawling and indexing work gives you the ability to diagnose visibility problems, prioritize technical fixes, and ensure your most important content gets the attention it deserves.
How AAMAX.CO Ensures Your Pages Get Crawled and Indexed
Technical issues that prevent crawling or indexing can quietly undermine an entire SEO strategy. AAMAX.CO is a full service digital marketing company that offers web development, digital marketing, and SEO services worldwide. Their technical specialists analyze crawl data, server logs, sitemaps, and Search Console reports to identify barriers that keep pages out of search results. Through their SEO services, they fix architecture problems, improve internal linking, and optimize crawl efficiency so important content is discovered and indexed quickly.
What Is Crawling?
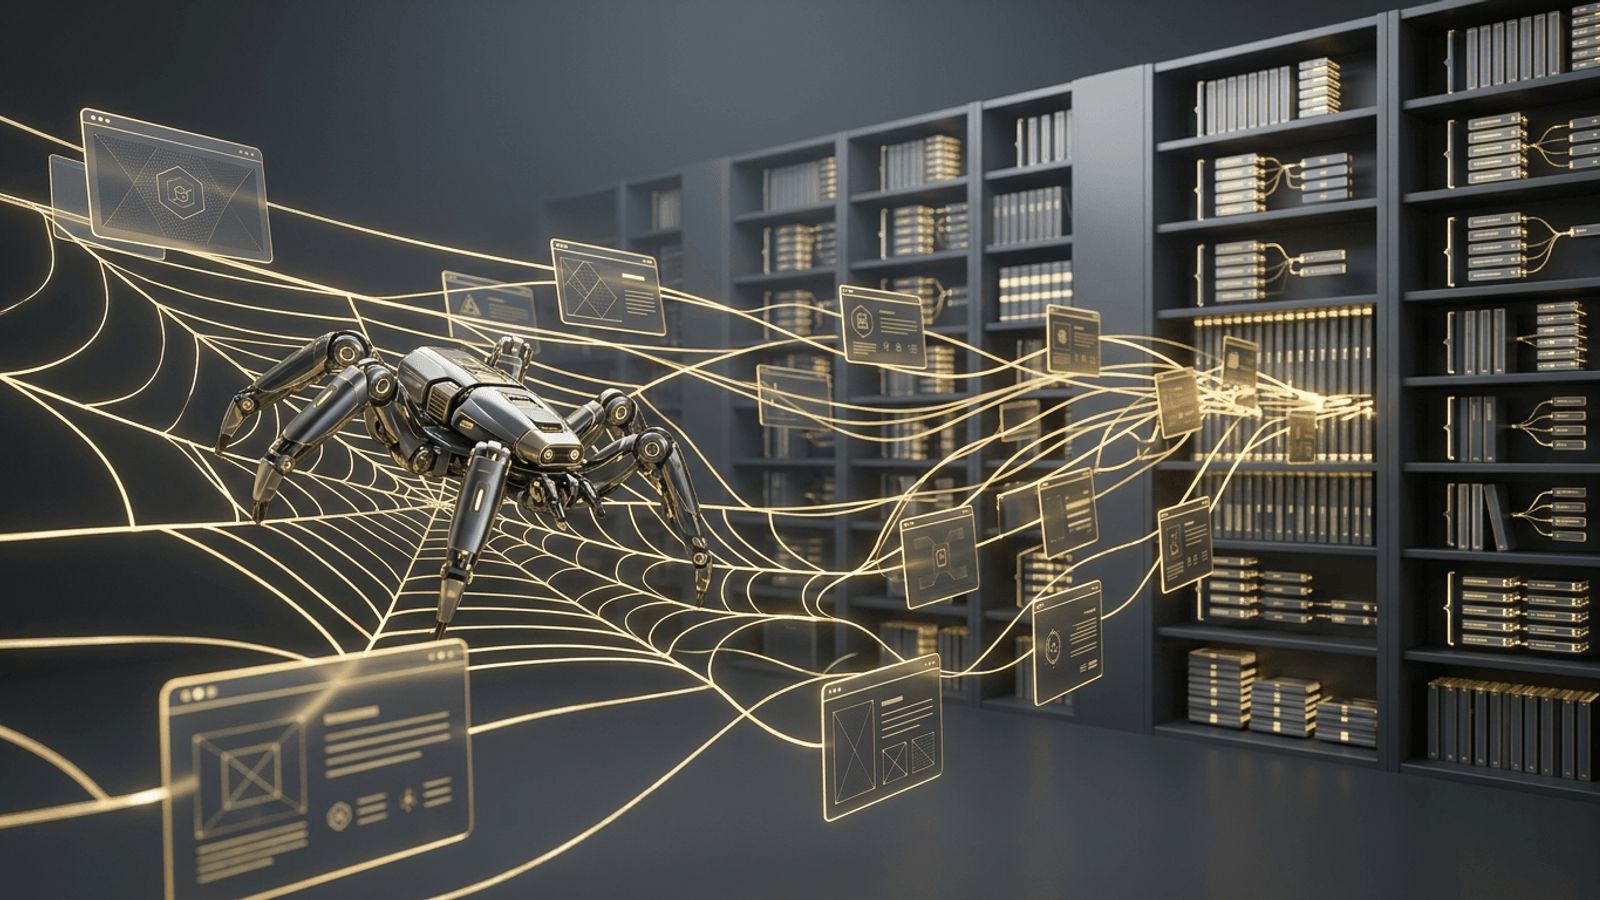
Crawling is the process by which search engines discover web pages. Search engines use bots, often called crawlers or spiders, such as Googlebot. These bots start with known URLs and follow links to find new and updated pages. They also use XML sitemaps submitted by website owners. When a crawler visits a page, it downloads the HTML, resources, and links, and may render JavaScript to see the final content.
What Is Indexing?
Indexing happens after crawling. The search engine analyzes the page content, including text, images, metadata, structured data, and links, and decides whether to store it in its index. The index is essentially a huge library of web pages organized so they can be retrieved quickly when someone searches. Not every crawled page is indexed. Search engines may skip pages that are duplicates, low quality, blocked by directives, or considered unhelpful.
The Difference Between Crawling and Indexing
Crawling is discovery; indexing is storage and understanding. A page can be crawled but not indexed if the search engine decides it lacks value or if a noindex tag tells it not to store the page. Conversely, a page blocked by robots.txt may not be crawled, although its URL can sometimes appear in the index without content if other sites link to it. Both steps must succeed for a page to compete in search results.
Common Crawling Problems
- Robots.txt blocks: Accidentally disallowing important directories or resources.
- Orphan pages: Pages with no internal links pointing to them.
- Broken links and redirect chains: Wasting crawler time and link equity.
- Slow server response: Causing crawlers to reduce their crawl rate.
- JavaScript-dependent links: Navigation that crawlers cannot follow easily.
Common Indexing Problems
Indexing issues often stem from noindex tags left on production pages, incorrect canonical tags pointing to other URLs, duplicate or near-duplicate content, thin pages with little unique value, and soft 404 errors. Google Search Console's page indexing report is the best place to identify these issues. It shows which URLs are indexed and explains why others are excluded, such as "Crawled, currently not indexed" or "Duplicate without user-selected canonical."
What Is Crawl Budget?
Crawl budget refers to the number of pages a search engine is willing and able to crawl on your site within a given timeframe. For small websites, crawl budget is rarely a concern. For large ecommerce stores, publishers, and sites with many parameter-based URLs, managing crawl budget becomes important. Reducing duplicate URLs, improving server speed, and blocking low-value pages help search engines focus on the content that matters.
How to Improve Crawling and Indexing
Create a clear site structure with logical categories and strong internal links. Submit and maintain an accurate XML sitemap. Use robots.txt carefully and review it after every site change. Apply canonical tags correctly to consolidate duplicates. Ensure important content is present in the initial HTML or rendered reliably. Improve page speed and server reliability. Publish helpful, original content that justifies indexing. These technical foundations make every other digital marketing effort more effective because new content becomes visible faster.
Crawling, Indexing, and AI Search
AI-powered search tools also depend on crawlable, indexable content. If AI crawlers cannot access your pages, your brand is less likely to be referenced in generated answers. Reviewing crawler access policies and structuring content clearly supports both traditional rankings and visibility in newer search experiences, which is the focus of GEO services.
Monitoring Crawl Activity
Search Console's crawl stats report shows how often Googlebot visits your website, how long responses take, and which file types are requested most. Large or complex sites can also analyze server log files to see exactly which URLs are crawled. These insights reveal whether crawlers are spending time on valuable pages or wasting resources on duplicates and parameters.
Conclusion
Crawling is how search engines discover your pages, and indexing is how they store and understand them. Both are prerequisites for ranking. By maintaining a clean architecture, accurate sitemaps, correct directives, fast performance, and genuinely useful content, you make it easy for search engines to find and index your website. Regular monitoring in Search Console ensures issues are caught early, protecting your organic visibility over time.
Want to publish a guest post on aamconsultants.org?
Place an order for a guest post or link insertion today.