Before a search engine can rank your pages, it must crawl them. The robots.txt file is one of the first things a crawler looks at when it visits your website, making it a small but powerful part of technical SEO. Used correctly, it guides search engines toward your most valuable content and away from areas that do not need to be crawled. Used incorrectly, it can accidentally hide your entire website from search results. This article explains what a robots.txt file is, how it works, and how to use it wisely.
Technical SEO Support From AAMAX.CO
Technical files like robots.txt may look simple, but a single misplaced character can have serious consequences for visibility. AAMAX.CO is a full-service digital marketing company offering web development, digital marketing, and SEO services worldwide. Their technical specialists audit crawl directives, sitemaps, indexing status, and site architecture to ensure search engines can access the content that matters most. Businesses seeking reliable SEO services that cover the technical foundations can count on them to configure these details correctly.
What Is a Robots.txt File?
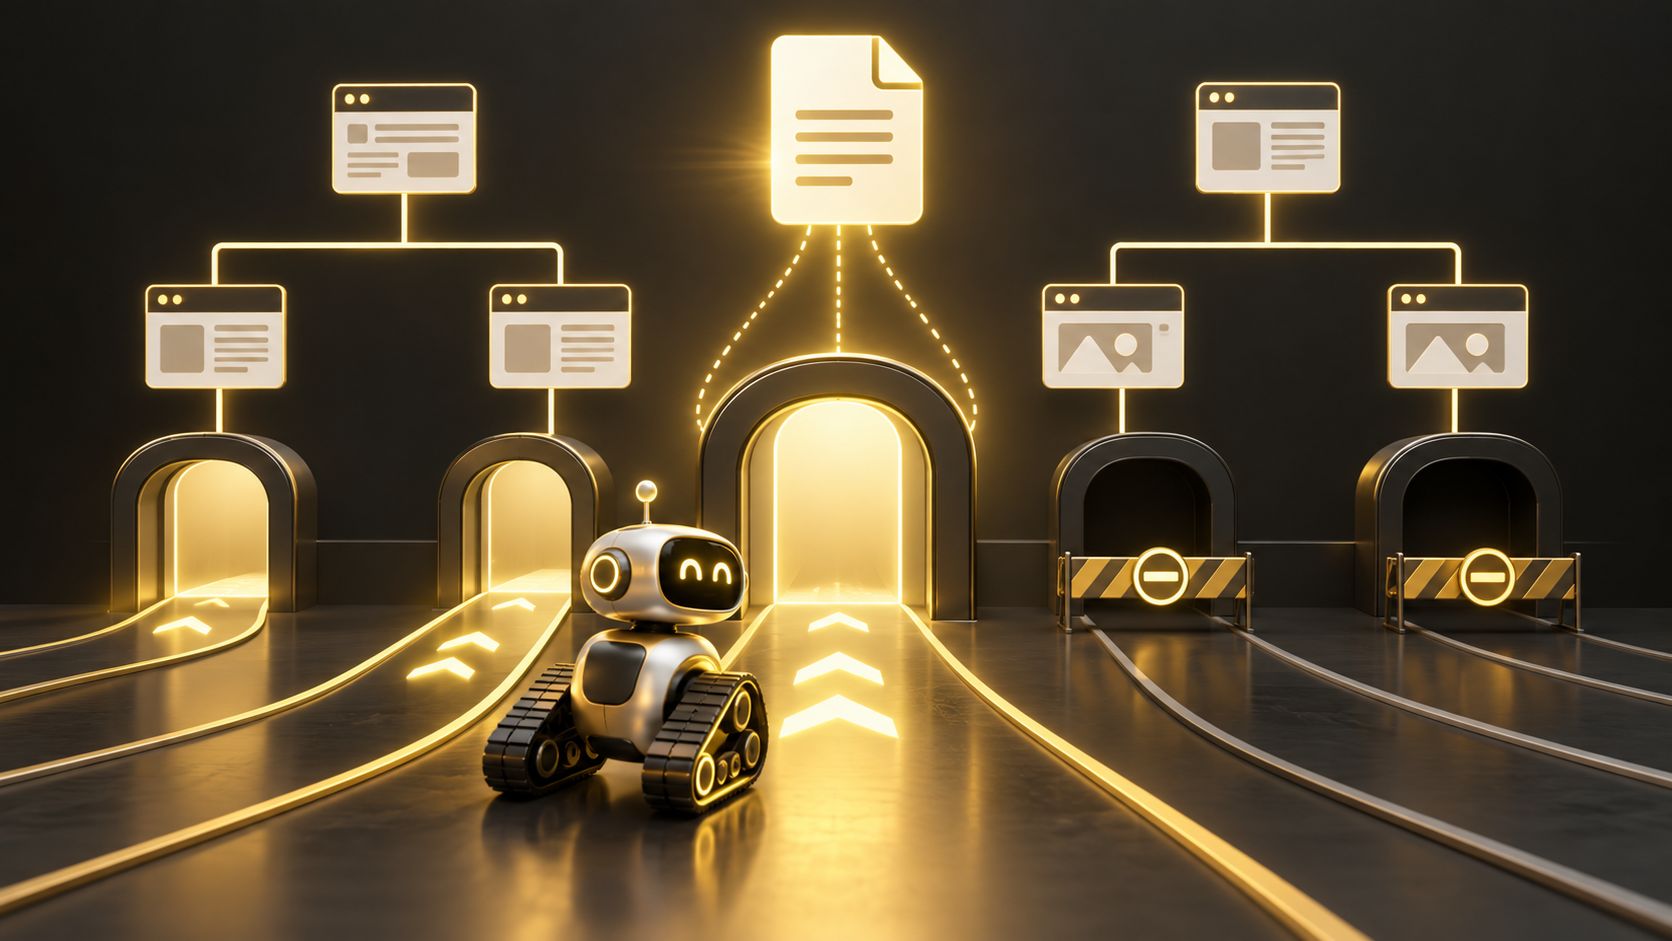
A robots.txt file is a plain text file placed in the root directory of a website, accessible at a URL like example.com/robots.txt. It follows the Robots Exclusion Protocol, a standard that tells web crawlers, also called bots or spiders, which URLs they are allowed to request. Search engines like Google and Bing check this file before crawling a site and generally follow its instructions. It is important to note that robots.txt controls crawling, not indexing, a distinction we will explore below.
How Robots.txt Works
When a crawler arrives at a website, it requests the robots.txt file first. If the file exists, the crawler reads the rules that apply to it and adjusts its behavior accordingly. If no file exists, crawlers assume they may crawl everything. Rules are organized into groups, each beginning with a user-agent line that specifies which crawler the rules apply to, followed by allow and disallow directives that define accessible and restricted paths.
Basic Robots.txt Syntax
User-agent: Identifies the crawler the rules apply to. An asterisk means all crawlers, while specific names like Googlebot or Bingbot target individual bots.
Disallow: Specifies a path that crawlers should not access. For example, "Disallow: /admin/" blocks the admin directory.
Allow: Permits access to a specific path within a disallowed directory. This is useful for making exceptions.
Sitemap: Provides the full URL of your XML sitemap, helping crawlers discover your important pages.
A simple example might include "User-agent: *" followed by "Disallow: /wp-admin/", "Allow: /wp-admin/admin-ajax.php", and a sitemap line pointing to your sitemap URL. Wildcards such as the asterisk and the dollar sign can also be used to match patterns, such as blocking all URLs containing certain parameters.
Why Robots.txt Matters for SEO
Managing crawl budget: Search engines allocate a limited amount of crawling resources to each site. For large websites, blocking low-value pages such as internal search results, filter combinations, or staging areas helps crawlers focus on important content.
Reducing duplicate crawling: Ecommerce sites often generate many URL variations through sorting and filtering parameters. Robots.txt can reduce wasted crawling on these near-duplicate pages.
Protecting server resources: Aggressive bots can strain servers. Restricting access to heavy or unnecessary areas can reduce load.
Guiding crawlers to sitemaps: Including your sitemap location makes content discovery more efficient.
Robots.txt Controls Crawling, Not Indexing
A common misunderstanding is that blocking a page in robots.txt removes it from search results. In reality, if other sites link to a blocked page, Google may still index the URL without crawling its content, sometimes displaying it with no description. To reliably keep a page out of search results, use a noindex meta tag or HTTP header instead, and make sure the page is not blocked in robots.txt, because crawlers must be able to access the page to see the noindex instruction. For truly sensitive content, use password protection.
Robots.txt and AI Crawlers
With the rise of generative AI, many new crawlers collect web content for training and answering questions. Site owners can use robots.txt to allow or block specific AI user agents. This decision has strategic implications. Blocking AI crawlers may protect content, but it can also reduce visibility in AI-generated answers. Businesses focused on being cited by AI assistants should consider GEO services to balance protection with discoverability.
Common Robots.txt Mistakes
Blocking the entire site: A rule like "Disallow: /" under "User-agent: *" blocks everything. This sometimes happens when a staging configuration is pushed to a live site.
Blocking CSS and JavaScript: Search engines need these resources to render pages correctly. Blocking them can hurt how Google understands and ranks your content.
Using robots.txt to hide private data: The file is publicly accessible, so listing sensitive directories can actually reveal them. Use authentication instead.
Conflicting rules: Overlapping allow and disallow directives can cause confusion. Keep rules simple and test them.
Wrong file location or name: The file must be named robots.txt in lowercase and placed in the root directory. Subdomains require their own files.
How to Create and Test a Robots.txt File
You can create robots.txt with any plain text editor and upload it to your site's root directory. Many content management systems and SEO plugins allow editing directly from the dashboard. After making changes, use the robots.txt report in Google Search Console to confirm Google can fetch the file and to identify errors. Test important URLs to ensure they are not unintentionally blocked. Review the file whenever your site structure changes.
Best Practices
Keep your robots.txt file concise and purposeful. Only block areas that genuinely do not need crawling. Always include your sitemap URL. Avoid blocking resources required for rendering. Use noindex for pages that should not appear in search results. Document changes so your team understands why each rule exists, and audit the file regularly as part of your technical SEO routine.
Conclusion
The robots.txt file is a simple text document with a significant impact on SEO. It tells search engine crawlers where they can and cannot go, helping manage crawl budget, reduce duplicate crawling, and point bots to your sitemap. By understanding its syntax, recognizing its limitations, and avoiding common mistakes, you can use robots.txt to support rather than sabotage your search visibility.
Want to publish a guest post on aamconsultants.org?
Place an order for a guest post or link insertion today.